
Men and women in California put their lives on the line when battling wildfires every year, but there is a future where machines powered by artificial intelligence are on the front lines, not firefighters.
However, this new generation of self-thinking robots would need security protocols to ensure they aren’t susceptible to hackers. To integrate such robots into society, they must come with assurances that they will behave safely around humans.
It begs the question: can you guarantee the safety of something that doesn’t exist yet? It’s something Assistant Professor Glen Chou hopes to accomplish by developing algorithms that will enable autonomous systems to learn and adapt while acting with safety and security assurances.
He plans to launch research initiatives, in collaboration with the School of Cybersecurity and Privacy and the Daniel Guggenheim School of Aerospace Engineering, to secure this new technological frontier as it develops.
“To operate in uncertain real-world environments, robots and other autonomous systems need to leverage and adapt a complex network of perception and control algorithms to turn sensor data into actions,” he said. “To obtain realistic assurances, we must do a joint safety and security analysis on these sensors and algorithms simultaneously, rather than one at a time.”
This end-to-end method would proactively look for flaws in the robot’s systems rather than wait for them to be exploited. This would lead to intrinsically robust robotic systems that can recover from failures.
Chou said this research will be useful in other domains, including advanced space exploration. If a space rover is sent to one of Saturn’s moons, for example, it needs to be able to act and think independently of scientists on Earth.
Aside from fighting fires and exploring space, this technology could perform maintenance in nuclear reactors, automatically maintain the power grid, and make autonomous surgery safer. It could also bring assistive robots into the home, enabling higher standards of care.
This is a challenging domain where safety, security, and privacy concerns are paramount due to frequent, close contact with humans.
This will start in the newly established Trustworthy Robotics Lab at Georgia Tech, which Chou directs. He and his Ph.D. students will design principled algorithms that enable general-purpose robots and autonomous systems to operate capably, safely, and securely with humans while remaining resilient to real-world failures and uncertainty.
Chou earned dual bachelor’s degrees in electrical engineering and computer sciences as well as mechanical engineering from University of California Berkeley in 2017, a master’s and Ph.D. in electrical and computer engineering from the University of Michigan in 2019 and 2022, respectively. He was a postdoc at MIT Computer Science & Artificial Intelligence Laboratory prior to joining Georgia Tech in November 2024. He is a recipient of the National Defense Science and Engineering Graduate fellowship program, NSF Graduate Research fellowships, and was named a Robotics: Science and Systems Pioneer in 2022.
News Contact
John (JP) Popham
Communications Officer II
College of Computing | School of Cybersecurity and Privacy
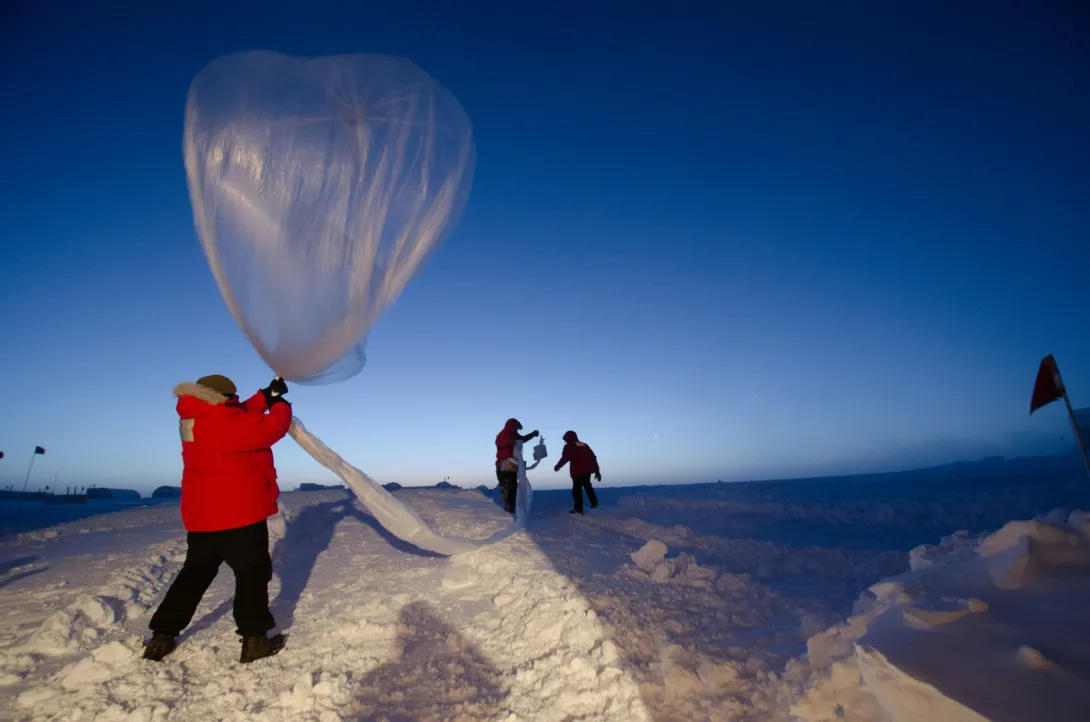
Researchers launch a a lightweight, balloon-borne instrument to collect data. "To keep advancing, we need scientists who can determine what data we need, collect that data, and solve problems," Bracco says. (NOAA)
Exponential growth in big data and computing power is transforming climate science, where machine learning is playing a critical role in mapping the physics of our changing climate.
“What is happening within the field is revolutionary,” says School of Earth and Atmospheric Sciences Associate Chair and Professor Annalisa Bracco, adding that because many climate-related processes — from ocean currents to melting glaciers and weather patterns — can be described with physical equations, these advancements have the potential to help us understand and predict climate in critically important ways.
Bracco is the lead author of a new review paper providing a comprehensive look at the intersection of AI and climate physics.
The result of an international collaboration between Georgia Tech’s Bracco, Julien Brajard (Nansen Environmental and Remote Sensing Center), Henk A. Dijkstra (Utrecht University), Pedram Hassanzadeh (University of Chicago), Christian Lessig (European Centre for Medium-Range Weather Forecasts), and Claire Monteleoni (University of Colorado Boulder), the paper, ‘Machine learning for the physics of climate,’ was recently published in Nature Reviews Physics.
“One of our team’s goals was to help people think deeply on how climate science and AI intersect,” Bracco shares. “Machine learning is allowing us to study the physics of climate in a way that was previously impossible. Coupled with increasing amounts of data and observations, we can now investigate climate at scales and resolutions we’ve never been able to before.”
Connecting hidden dots
The team showed that ML is driving change in three key areas: accounting for missing observational data, creating more robust climate models, and enhancing predictions, especially in weather forecasting. However, the research also underscores the limits of AI — and how researchers can work to fill those gaps.
“Machine learning has been fantastic in allowing us to expand the time and the spatial scales for which we have measurements,” says Bracco, explaining that ML could help fill in missing data points — creating a more robust record for researchers to reference. However, like patching a hole in a shirt, this works best when the rest of the material is intact.
“Machine learning can extrapolate from past conditions when observations are abundant, but it can’t yet predict future trends or collect the data we need,” Bracco adds. “To keep advancing, we need scientists who can determine what data we need, collect that data, and solve problems.”
Modeling climate, predicting weather
Machine learning is often used when improving climate models that can simulate changing systems like our atmosphere, oceans, land, biochemistry, and ice. “These models are limited because of our computing power, and are run on a three-dimensional grid,” Bracco explains: below the grid resolution, researchers need to approximate complex physics with simpler equations that computers can solve quickly, a process called ‘parameterization’.
Machine learning is changing that, offering new ways to improve parameterizations, she says. “We can run a model at extremely high resolutions for a short time, so that we don’t need to parameterize as many physical processes — using machine learning to derive the equations that best approximate what is happening at small scales,” she explains. “Then we can use those equations in a coarser model that we can run for hundreds of years.”
While a full climate model based solely on machine learning may remain out of reach, the team found that ML is advancing our ability to accurately predict weather systems and some climate phenomena like El Niño.
Previously, weather prediction was based on knowing the starting conditions — like temperature, humidity, and barometric pressure — and running a model based on physics equations to predict what might happen next. Now, machine learning is giving researchers the opportunity to learn from the past. “We can use information on what has happened when there were similar starting conditions in previous situations to predict the future without solving the underlying governing equations,” Bracco says. “And all while using orders-of-magnitude less computing resources.”
The human connection
Bracco emphasizes that while AI and ML play a critical role in accelerating research, humans are at the core of progress. “I think the in-person collaboration that led to this paper is, in itself, a testament to the importance of human interaction,” she says, recalling that the research was the result of a workshop organized at the Kavli Institute for Theoretical Physics — one of the team’s first in-person discussions after the Covid-19 pandemic.
“Machine learning is a fantastic tool — but it's not the solution to everything,” she adds. “There is also a real need for human researchers collecting high-quality data, and for interdisciplinary collaboration across fields. I see this as a big challenge, but a great opportunity for computer scientists and physicists, mathematicians, biologists, and chemists to work together.”
Funding: National Science Foundation, European Research Council, Office of Naval Research, US Department of Energy, European Space Agency, Choose France Chair in AI.
DOI: https://doi.org/10.1038/s42254-024-00776-3
News Contact
Written by Selena Langner
Effective January 1st, David Sherrill will serve as interim executive director of the Georgia Tech Institute for Data Engineering and Science (IDEaS). Sherrill is a Regents' Professor in the School of Chemistry and Biochemistry with a joint appointment in the College of Computing. Sherrill has served as associate director for IDEaS since its founding in 2016.
"David Sherrill's leadership role in IDEaS as associate director, together with his interdisciplinary background in chemistry and computer science, makes him the right person to support this transition as interim executive director," said Julia Kubanek, professor and vice president for interdisciplinary research at Georgia Tech.
Sherrill succeeds Srinivas Aluru who will be taking a new position as Senior Associate Dean in the College of Computing. Aluru, a Regents' Professor in the School of Computational Science and Engineering, co-founded IDEaS and served as its co-executive director (2016-2019) and then as executive director (2019-date), spanning eight and a half years. Under his leadership IDEaS grew to more than 200 affiliate faculty spanning all colleges, encompassing multiple state, federal, and industry funded centers. Notable among these is the South Big Data Hub, catalyzing the Southern data science community to collectively accelerate scientific discovery and innovation, spur economic development in the region, broaden participation and diversity in data science, and the CloudHub, a Microsoft funded center that provides research funding and cloud resources for innovative applications in Generative Artificial Intelligence. More recently, Aluru established the Center for Artificial Intelligence in Science and Engineering (ARTISAN), and expanded the Institute’s research staff to provide needed cyberinfrastructure, software resources, and expertise to support faculty projects with large data sets and AI-driven discovery. "I've had the pleasure of serving as Associate Director of IDEaS since it was founded by Srinivas Aluru and Dana Randall, and I'm excited to step into this interim role.” said Sherrill. “IDEaS has an important mission to serve the many faculty doing interdisciplinary research involving data science and high performance computing."
Sherrill’s research group focuses on the development of ab initio electronic structure theory and its application to problems of broad chemical interest, including the influence of non-covalent interactions in drug binding, biomolecular structure, organic crystals, and organocatalytic transition states. The group seeks to apply the most accurate quantum models possible for a given problem and specializes in generating high-quality datasets for testing new methods or machine-learning purposes.
Sherrill earned a B.S. in chemistry from MIT in 1992 and a Ph.D. in chemistry from the University of Georgia in 1996. From 1996-1999 Sherril was an NSF Postdoctoral Fellow, working under M. Head-Gordon, at the University of California, Berkeley.
Sherrill is a Fellow of the American Association for the Advancement of Science (AAAS), the American Chemical Society, and the American Physical Society, and he has been Associate Editor of the Journal of Chemical Physics since 2009. Sherrill has received a Camille and Henry Dreyfus New Faculty Award, the International Journal of Quantum Chemistry Young Investigator Award, an NSF CAREER Award, and Georgia Tech's W. Howard Ector Outstanding Teacher Award. In 2023, he received the Herty Medal from the Georgia Section of the American Chemical Society, and in 2024, he was elected to the International Academy of Quantum Molecular Science.
--Christa M. Ernst
News Contact
Christa M. Ernst [christa.ernst@research.gatech.edu],
Research Communications Program Manager,
Topic Expertise: Robotics | Data Sciences| Semiconductor Design & Fab
The National Science Foundation has released the results of its annual Higher Education Research and Development Survey (HERD), and Georgia Tech has once again moved up again in the rankings.
The survey of U.S. university research and development expenditures places Georgia Tech as No. 16, up from No. 17 last year, and No. 1 among universities without a medical school. The Institute ranks No. 3 for federally funded research, up from No. 5, and is No. 7 for all externally funded research, up from No. 9.
“Georgia Tech's continued ascension in research rankings is a testament to the exceptional dedication and collaboration of our faculty, staff, and research sponsors,” said Tim Lieuwen, interim executive vice president for Research. “This trajectory, particularly our rise in federally and externally funded research, amplifies the confidence our partners have in Georgia Tech tackle society’s biggest challenges.”
The annual survey compiles R&D expenditure data from U.S. colleges and universities with more than $150,000 in research expenditures during a fiscal year. For fiscal year 2023 (July 1, 2022 – June 30, 2023), that included 914 institutions. Overall, U.S. higher-education R&D spending rose by 11.2%, exceeding $108 billion in fiscal year 2023. This is the largest increase since 2003.
Georgia Tech’s R&D spending of $1.45 billion in fiscal year 2023 reflects an impressive 17.9% increase — $219 million more — from the previous year for the entire research enterprise, which includes the Georgia Tech Research Institute (GTRI). GTRI remains the largest contributor to Georgia Tech’s growth and continues to play a major role in the Institute’s research enterprise and in national defense research.
Additionally, Georgia Tech’s R&D expenditures contributed a monumental $1.45 billion to the state of Georgia’s economy, along with continued growth in commercialization efforts that bring technologies out of the lab and into to the world.
Lieuwen said, “I am proud of these standings and even more excited about the possibilities ahead as we continue to drive innovation that benefits our state, the nation, and the world.”
About Georgia Tech’s Office of the Executive Vice President for Research
The Office of the Executive Vice President for Research (EVPR) directs Georgia Tech’s $1.37 billion (FY 2024) portfolio of research, development, and sponsored activities. This includes leadership of the Georgia Tech Research Institute (GTRI), the Enterprise Innovation Institute, nine interdisciplinary research institutes (IRIs) plus research centers, and related research administrative support units: commercialization, corporate engagement, research development and operations, and research administration. Georgia Tech routinely ranks among the top U.S. universities in volume of research conducted.
News Contact
Shelley Wunder-Smith | shelley.wunder-smith@research.gatech.edu
Director of Research Communications
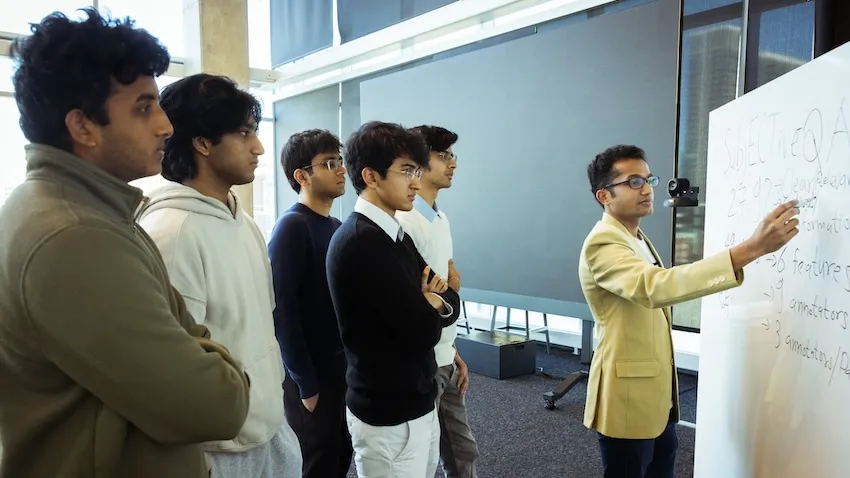
Georgia Tech researchers have created a dataset that trains computer models to understand nuances in human speech during financial earnings calls. The dataset provides a new resource to study how public correspondence affects businesses and markets.
SubjECTive-QA is the first human-curated dataset on question-answer pairs from earnings call transcripts (ECTs). The dataset teaches models to identify subjective features in ECTs, like clarity and cautiousness.
The dataset lays the foundation for a new approach to identifying disinformation and misinformation caused by nuances in speech. While ECT responses can be technically true, unclear or irrelevant information can misinform stakeholders and affect their decision-making.
Tests on White House press briefings showed that the dataset applies to other sectors with frequent question-and-answer encounters, notably politics, journalism, and sports. This increases the odds of effectively informing audiences and improving transparency across public spheres.
The intersecting work between natural language processing and finance earned the paper acceptance to NeurIPS 2024, the 38th Annual Conference on Neural Information Processing Systems. NeurIPS is one of the world’s most prestigious conferences on artificial intelligence (AI) and machine learning (ML) research.
"SubjECTive-QA has the potential to revolutionize nowcasting predictions with enhanced clarity and relevance,” said Agam Shah, the project’s lead researcher.
“Its nuanced analysis of qualities in executive responses, like optimism and cautiousness, deepens our understanding of economic forecasts and financial transparency."
[MICROSITE: Georgia Tech at NeurIPS 2024]
SubjECTive-QA offers a new means to evaluate financial discourse by characterizing language's subjective and multifaceted nature. This improves on traditional datasets that quantify sentiment or verify claims from financial statements.
The dataset consists of 2,747 Q&A pairs taken from 120 ECTs from companies listed on the New York Stock Exchange from 2007 to 2021. The Georgia Tech researchers annotated each response by hand based on six features for a total of 49,446 annotations.
The group evaluated answers on:
- Relevance: the speaker answered the question with appropriate details.
- Clarity: the speaker was transparent in the answer and the message conveyed.
- Optimism: the speaker answered with a positive outlook regarding future outcomes.
- Specificity: the speaker included sufficient and technical details in their answer.
- Cautiousness: the speaker answered using a conservative, risk-averse approach.
- Assertiveness: the speaker answered with certainty about the company’s events and outcomes.
The Georgia Tech group validated their dataset by training eight computer models to detect and score these six features. Test models comprised of three BERT-based pre-trained language models (PLMs), and five popular large language models (LLMs) including Llama and ChatGPT.
All eight models scored the highest on the relevance and clarity features. This is attributed to domain-specific pretraining that enables the models to identify pertinent and understandable material.
The PLMs achieved higher scores on the clear, optimistic, specific, and cautious categories. The LLMs scored higher in assertiveness and relevance.
In another experiment to test transferability, a PLM trained with SubjECTive-QA evaluated 65 Q&A pairs from White House press briefings and gaggles. Scores across all six features indicated models trained on the dataset could succeed in other fields outside of finance.
"Building on these promising results, the next step for SubjECTive-QA is to enhance customer service technologies, like chatbots,” said Shah, a Ph.D. candidate studying machine learning.
“We want to make these platforms more responsive and accurate by integrating our analysis techniques from SubjECTive-QA."
SubjECTive-QA culminated from two semesters of work through Georgia Tech’s Vertically Integrated Projects (VIP) Program. The VIP Program is an approach to higher education where undergraduate and graduate students work together on long-term project teams led by faculty.
Undergraduate students earn academic credit and receive hands-on experience through VIP projects. The extra help advances ongoing research and gives graduate students mentorship experience.
Computer science major Huzaifa Pardawala and mathematics major Siddhant Sukhani co-led the SubjECTive-QA project with Shah.
Fellow collaborators included Veer Kejriwal, Abhishek Pillai, Rohan Bhasin, Andrew DiBiasio, Tarun Mandapati, and Dhruv Adha. All six researchers are undergraduate students studying computer science.
Sudheer Chava co-advises Shah and is the faculty lead of SubjECTive-QA. Chava is a professor in the Scheller College of Business and director of the M.S. in Quantitative and Computational Finance (QCF) program.
Chava is also an adjunct faculty member in the College of Computing’s School of Computational Science and Engineering (CSE).
"Leading undergraduate students through the VIP Program taught me the powerful impact of balancing freedom with guidance,” Shah said.
“Allowing students to take the helm not only fosters their leadership skills but also enhances my own approach to mentoring, thus creating a mutually enriching educational experience.”
Presenting SubjECTive-QA at NeurIPS 2024 exposes the dataset for further use and refinement. NeurIPS is one of three primary international conferences on high-impact research in AI and ML. The conference occurs Dec. 10-15.
The SubjECTive-QA team is among the 162 Georgia Tech researchers presenting over 80 papers at NeurIPS 2024. The Georgia Tech contingent includes 46 faculty members, like Chava. These faculty represent Georgia Tech’s Colleges of Business, Computing, Engineering, and Sciences, underscoring the pertinence of AI research across domains.
"Presenting SubjECTive-QA at prestigious venues like NeurIPS propels our research into the spotlight, drawing the attention of key players in finance and tech,” Shah said.
“The feedback we receive from this community of experts validates our approach and opens new avenues for future innovation, setting the stage for transformative applications in industry and academia.”
News Contact
Bryant Wine, Communications Officer
bryant.wine@cc.gatech.edu
A new machine learning (ML) model from Georgia Tech could protect communities from diseases, better manage electricity consumption in cities, and promote business growth, all at the same time.
Researchers from the School of Computational Science and Engineering (CSE) created the Large Pre-Trained Time-Series Model (LPTM) framework. LPTM is a single foundational model that completes forecasting tasks across a broad range of domains.
Along with performing as well or better than models purpose-built for their applications, LPTM requires 40% less data and 50% less training time than current baselines. In some cases, LPTM can be deployed without any training data.
The key to LPTM is that it is pre-trained on datasets from different industries like healthcare, transportation, and energy. The Georgia Tech group created an adaptive segmentation module to make effective use of these vastly different datasets.
The Georgia Tech researchers will present LPTM in Vancouver, British Columbia, Canada, at the 2024 Conference on Neural Information Processing Systems (NeurIPS 2024). NeurIPS is one of the world’s most prestigious conferences on artificial intelligence (AI) and ML research.
“The foundational model paradigm started with text and image, but people haven’t explored time-series tasks yet because those were considered too diverse across domains,” said B. Aditya Prakash, one of LPTM’s developers.
“Our work is a pioneer in this new area of exploration where only few attempts have been made so far.”
[MICROSITE: Georgia Tech at NeurIPS 2024]
Foundational models are trained with data from different fields, making them powerful tools when assigned tasks. Foundational models drive GPT, DALL-E, and other popular generative AI platforms used today. LPTM is different though because it is geared toward time-series, not text and image generation.
The Georgia Tech researchers trained LPTM on data ranging from epidemics, macroeconomics, power consumption, traffic and transportation, stock markets, and human motion and behavioral datasets.
After training, the group pitted LPTM against 17 other models to make forecasts as close to nine real-case benchmarks. LPTM performed the best on five datasets and placed second on the other four.
The nine benchmarks contained data from real-world collections. These included the spread of influenza in the U.S. and Japan, electricity, traffic, and taxi demand in New York, and financial markets.
The competitor models were purpose-built for their fields. While each model performed well on one or two benchmarks closest to its designed purpose, the models ranked in the middle or bottom on others.
In another experiment, the Georgia Tech group tested LPTM against seven baseline models on the same nine benchmarks in zero-shot forecasting tasks. Zero-shot means the model is used out of the box and not given any specific guidance during training. LPTM outperformed every model across all benchmarks in this trial.
LPTM performed consistently as a top-runner on all nine benchmarks, demonstrating the model’s potential to achieve superior forecasting results across multiple applications with less and resources.
“Our model also goes beyond forecasting and helps accomplish other tasks,” said Prakash, an associate professor in the School of CSE.
“Classification is a useful time-series task that allows us to understand the nature of the time-series and label whether that time-series is something we understand or is new.”
One reason traditional models are custom-built to their purpose is that fields differ in reporting frequency and trends.
For example, epidemic data is often reported weekly and goes through seasonal peaks with occasional outbreaks. Economic data is captured quarterly and typically remains consistent and monotone over time.
LPTM’s adaptive segmentation module allows it to overcome these timing differences across datasets. When LPTM receives a dataset, the module breaks data into segments of different sizes. Then, it scores all possible ways to segment data and chooses the easiest segment from which to learn useful patterns.
LPTM’s performance, enhanced through the innovation of adaptive segmentation, earned the model acceptance to NeurIPS 2024 for presentation. NeurIPS is one of three primary international conferences on high-impact research in AI and ML. NeurIPS 2024 occurs Dec. 10-15.
Ph.D. student Harshavardhan Kamarthi partnered with Prakash, his advisor, on LPTM. The duo are among the 162 Georgia Tech researchers presenting over 80 papers at the conference.
Prakash is one of 46 Georgia Tech faculty with research accepted at NeurIPS 2024. Nine School of CSE faculty members, nearly one-third of the body, are authors or co-authors of 17 papers accepted at the conference.
Along with sharing their research at NeurIPS 2024, Prakash and Kamarthi released an open-source library of foundational time-series modules that data scientists can use in their applications.
“Given the interest in AI from all walks of life, including business, social, and research and development sectors, a lot of work has been done and thousands of strong papers are submitted to the main AI conferences,” Prakash said.
“Acceptance of our paper speaks to the quality of the work and its potential to advance foundational methodology, and we hope to share that with a larger audience.”
News Contact
Bryant Wine, Communications Officer
bryant.wine@cc.gatech.edu
Deven Desai and Mark Riedl have seen the signs for a while.
Two years since OpenAI introduced ChatGPT, dozens of lawsuits have been filed alleging technology companies have infringed copyright by using published works to train artificial intelligence (AI) models.
Academic AI research efforts could be significantly hindered if courts rule in the plaintiffs' favor.
Desai and Riedl are Georgia Tech researchers raising awareness about how these court rulings could force academic researchers to construct new AI models with limited training data. The two collaborated on a benchmark academic paper that examines the landscape of the ethical issues surrounding AI and copyright in industry and academic spaces.
“There are scenarios where courts may overreact to having a book corpus on your computer, and you didn’t pay for it,” Riedl said. “If you trained a model for an academic paper, as my students often do, that’s not a problem right now. The courts could deem training is not fair use. That would have huge implications for academia.
“We want academics to be free to do their research without fear of repercussions in the marketplace because they’re not competing in the marketplace,” Riedl said.
Desai is the Sue and John Stanton Professor of Business Law and Ethics at the Scheller College of Business. He researches how business interests and new technology shape privacy, intellectual property, and competition law. Riedl is a professor at the College of Computing’s School of Interactive Computing, researching human-centered AI, generative AI, explainable AI, and gaming AI.
Their paper, Between Copyright and Computer Science: The Law and Ethics of Generative AI, was published in the Northwestern Journal of Technology and Intellectual Property on Monday.
Desai and Riedl say they want to offer solutions that balance the interests of various stakeholders. But that requires compromise from all sides.
Researchers should accept they may have to pay for the data they use to train AI models. Content creators, on the other hand, should receive compensation, but they may need to accept less money to ensure data remains affordable for academic researchers to acquire.
Who Benefits?
The doctrine of fair use is at the center of every copyright debate. According to the U.S. Copyright Office, fair use permits the unlicensed use of copyright-protected works in certain circumstances, such as distributing information for the public good, including teaching and research.
Fair use is often challenged when one or more parties profit from published works without compensating the authors.
Any original published content, including a personal website on the internet, is protected by copyright. However, copyrighted material is republished on websites or posted on social media innumerable times every day without the consent of the original authors.
In most cases, it’s unlikely copyright violators gained financially from their infringement.
But Desai said business-to-business cases are different. The New York Times is one of many daily newspapers and media companies that have sued OpenAI for using its content as training data. Microsoft is also a defendant in The New York Times’ suit because it invested billions of dollars into OpenAI’s development of AI tools like ChatGPT.
“You can take a copyrighted photo and put it in your Twitter post or whatever you want,” Desai said. “That’s probably annoying to the owner. Economically, they probably wanted to be paid. But that’s not business to business. What’s happening with Open AI and The New York Times is business to business. That’s big money.”
OpenAI started as a nonprofit dedicated to the safe development of artificial general intelligence (AGI) — AI that, in theory, can rival human thinking and possess autonomy.
These AI models would require massive amounts of data and expensive supercomputers to process that data. OpenAI could not raise enough money to afford such resources, so it created a for-profit arm controlled by its parent nonprofit.
Desai, Riedl, and many others argue that OpenAI ceased its research mission for the public good and began developing consumer products.
“If you’re doing basic research that you’re not releasing to the world, it doesn’t matter if every so often it plagiarizes The New York Times,” Riedl said. “No one is economically benefitting from that. When they became a for-profit and produced a product, now they were making money from plagiarized text.”
OpenAI’s for-profit arm is valued at $80 billion, but content creators have not received a dime since the company has scraped massive amounts of copyrighted material as training data.
The New York Times has posted warnings on its sites that its content cannot be used to train AI models. Many other websites offer a robot.txt file that contains instructions for bots about which pages can and cannot be accessed.
Neither of these measures are legally binding and are often ignored.
Solutions
Desai and Riedl offer a few options for companies to show good faith in rectifying the situation.
- Spend the money. Desai says Open AI and Microsoft could have afforded its training data and avoided the hassle of legal consequences.
“If you do the math on the costs to buy the books and copy them, they could have paid for them,” he said. “It would’ve been a multi-million dollar investment, but they’re a multi-billion dollar company.”
- Be selective. Models can be trained on randomly selected texts from published works, allowing the model to understand the writing style without plagiarizing.
“I don’t need the entire text of War and Peace,” Desai said. “To capture the way authors express themselves, I might only need a hundred pages. I’ve also reduced the chance that my model will cough up entire texts.”
- Leverage libraries. The authors agree libraries could serve as an ideal middle ground as a place to store published works and compensate authors for access to those works, though the amount may be less than desired.
“Most of the objections you could raise are taken care of,” Desai said. “They are legitimate access copies that are secure. You get access to only as much as you need. Libraries at universities have already become schools of information.”
Desai and Riedl hope the legal action taken by publications like The New York Times will send a message to companies that develop AI tools to pump the breaks. If they don’t, researchers uninterested in profit could pay the steepest price.
The authors say it’s not a new problem but is reaching a boiling point.
“In the history of copyright, there are ways that society has dealt with the problem of compensating creators and technology that copies or reduces your ability to extract money from your creation,” Desai said. “We wanted to point out there’s a way to get there.”
News Contact
Nathan Deen
Communications Officer
School of Interactive Computing
School of IC's Josiah Hester (left) and Cindy Lin discuss AI's future impact on sustainability. Photo by Terence Rushin/College of Computing.
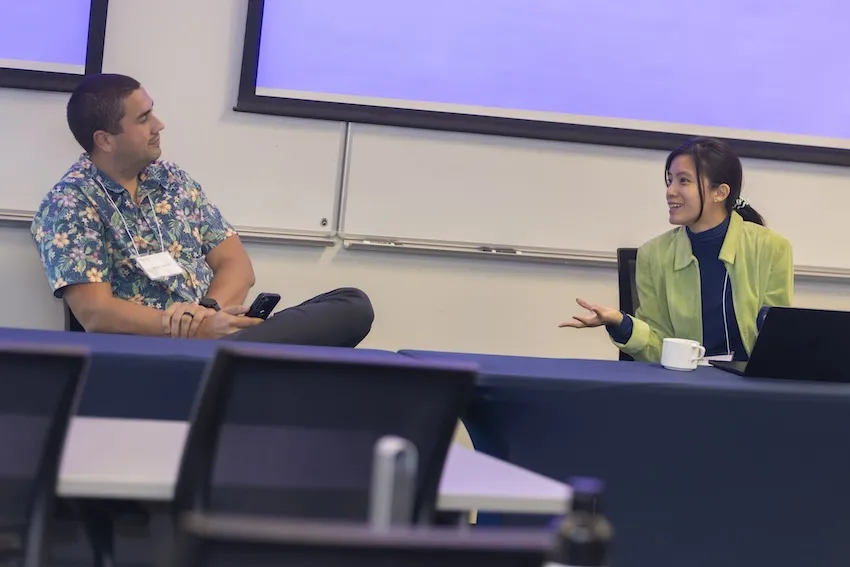
This month, the future of artificial intelligence (AI) was spotlighted as more than 120 academic and industry researchers participated in the Georgia Tech School of Interactive Computing’s inaugural Summit on Responsible Computing, AI, and Society.
With looming questions about AI's growing roles and consequences in nearly every facet of modern life, School of IC organizers felt the time was right to diverge from traditional conferences that focus on past work and published research.
“Presenting papers is about disseminating work that has already been completed. Who gets to be in the room is determined by whose paper gets accepted,” said Mark Riedl, School of IC professor.
“Instead, we wanted the summit talks to speculate on future directions and what challenges we as a community should be thinking about going forward.”
The two-day summit, held at Tech’s Global Learning Center Oct. 28-30, convened to discuss consequential questions like:
- Is society ready to accept more responsibility as greater advancements in technologies like AI are made?
- Should society stop to think about potential consequences before these advancements are implemented on its behalf, and what could those consequences be?
- What policies should be enacted for these technologies to mitigate harms and augment societal benefits?
A highlight of the summit’s opening day was Meredith Ringel Morris's keynote address. As director of human-AI interaction research at Google DeepMind, she presented a possible future in which humans could use AI to create a digital afterlife.
In her remarks, Morris discussed AI clones, which are AI avatars of specific human beings with high autonomy and task-performing capabilities. Someone could leave such an agent behind as a memory for loved ones to enjoy once they are gone, and future generations could access it to learn more about an ancestor.
On the other hand, it could easily lead to loved ones experiencing extended grief because they have trouble moving on from losing a family member.
These AI capabilities are in development and will soon be publicly available. As industry and academic researchers continue to develop them, the public needs to learn about their eminent impacts.
“There’s a lot that needs to be done in educating people,” Morris said. “It’s hard for well-intentioned and thoughtful system designers to anticipate all the harm. We must be prepared some people are going to use AI in ways we don’t anticipate, and some of those ways are going to be undesirable. What legal and education structures can we create that will help?”
In addition to Morris’s keynote, the summit’s first day included 20 talks about future and emerging technologies in AI, sustainability, healthcare, and other fields.
The second day featured eight talks on translating interventions and safeguards into policy.
Day-two speakers included:
- Orly Lobel, Warren Distinguished Professor of Law and director of the Center for Employment and Labor Policy at the University of California-San Diego. Lobel worked on President Obama’s policy team on innovation and labor market competition, and she advises the Federal Trade Commission (FTC).
- Sorelle Friedler, Shibulal Family Professor of Computer Science at Haverford College. She worked in the Office of Science and Technology Policy (OSTP) under the Biden-Harris Administration and helped draft the AI Bill of Rights.
- Jake Metcalf, researcher and program director for AI on the Ground at the think tank Data & Society. The organization produces reports on data science and equity for the US Government.
- Divyansh Kaushik, Vice President of Beacon Global Strategies, has given testimony to the US Senate on AI research and development.
Kaushik earned a Ph.D. in machine learning from Carnegie Mellon University before beginning his career in policy. He highlighted the importance of policymakers fostering relationships with academic researchers.
“Policymakers think about what could go wrong,” Kaushik said. “Academia can offer evidence-based answers.”
The summit also hosted a doctoral consortium, which allowed advanced Ph.D. students to present their research to experts and receive feedback and mentoring.
“Being an interdisciplinary researcher is challenging,” said Shaowen Bardzell, School of IC chair.
“We wanted the next generation to be in the room listening to the experts share their visions and also to provide our own experiences when possible on how to navigate the challenges and rewards of doing work in the intersection of AI, healthcare, sustainability, and policy.”
News Contact
Nathan Deen
Georgia Tech School of Interactive Computing
Communications Officer
nathan.deen@cc.gatech.edu
The U.S. Department of Energy (DOE) has awarded Georgia Tech researchers a $4.6 million grant to develop improved cybersecurity protection for renewable energy technologies.
Associate Professor Saman Zonouz will lead the project and leverage the latest artificial technology (AI) to create Phorensics. The new tool will anticipate cyberattacks on critical infrastructure and provide analysts with an accurate reading of what vulnerabilities were exploited.
“This grant enables us to tackle one of the crucial challenges facing national security today: our critical infrastructure resilience and post-incident diagnostics to restore normal operations in a timely manner,” said Zonouz.
“Together with our amazing team, we will focus on cyber-physical data recovery and post-mortem forensics analysis after cybersecurity incidents in emerging renewable energy systems.”
As the integration of renewable energy technology into national power grids increases, so does their vulnerability to cyberattacks. These threats put energy infrastructure at risk and pose a significant danger to public safety and economic stability. The AI behind Phorensics will allow analysts and technicians to scale security efforts to keep up with a growing power grid that is becoming more complex.
This effort is part of the Security of Engineering Systems (SES) initiative at Georgia Tech’s School of Cybersecurity and Privacy (SCP). SES has three pillars: research, education, and testbeds, with multiple ongoing large, sponsored efforts.
“We had a successful hiring season for SES last year and will continue filling several open tenure-track faculty positions this upcoming cycle,” said Zonouz.
“With top-notch cybersecurity and engineering schools at Georgia Tech, we have begun the SES journey with a dedicated passion to pursue building real-world solutions to protect our critical infrastructures, national security, and public safety.”
Zonouz is the director of the Cyber-Physical Systems Security Laboratory (CPSec) and is jointly appointed by Georgia Tech’s School of Cybersecurity and Privacy (SCP) and the School of Electrical and Computer Engineering (ECE).
The three Georgia Tech researchers joining him on this project are Brendan Saltaformaggio, associate professor in SCP and ECE; Taesoo Kim, jointly appointed professor in SCP and the School of Computer Science; and Animesh Chhotaray, research scientist in SCP.
Katherine Davis, associate professor at the Texas A&M University Department of Electrical and Computer Engineering, has partnered with the team to develop Phorensics. The team will also collaborate with the NREL National Lab, and industry partners for technology transfer and commercialization initiatives.
The Energy Department defines renewable energy as energy from unlimited, naturally replenished resources, such as the sun, tides, and wind. Renewable energy can be used for electricity generation, space and water heating and cooling, and transportation.
News Contact
John Popham
Communications Officer II
College of Computing | School of Cybersecurity and Privacy
A new algorithm tested on NASA’s Perseverance Rover on Mars may lead to better forecasting of hurricanes, wildfires, and other extreme weather events that impact millions globally.
Georgia Tech Ph.D. student Austin P. Wright is first author of a paper that introduces Nested Fusion. The new algorithm improves scientists’ ability to search for past signs of life on the Martian surface.
In addition to supporting NASA’s Mars 2020 mission, scientists from other fields working with large, overlapping datasets can use Nested Fusion’s methods toward their studies.
Wright presented Nested Fusion at the 2024 International Conference on Knowledge Discovery and Data Mining (KDD 2024) where it was a runner-up for the best paper award. KDD is widely considered the world's most prestigious conference for knowledge discovery and data mining research.
“Nested Fusion is really useful for researchers in many different domains, not just NASA scientists,” said Wright. “The method visualizes complex datasets that can be difficult to get an overall view of during the initial exploratory stages of analysis.”
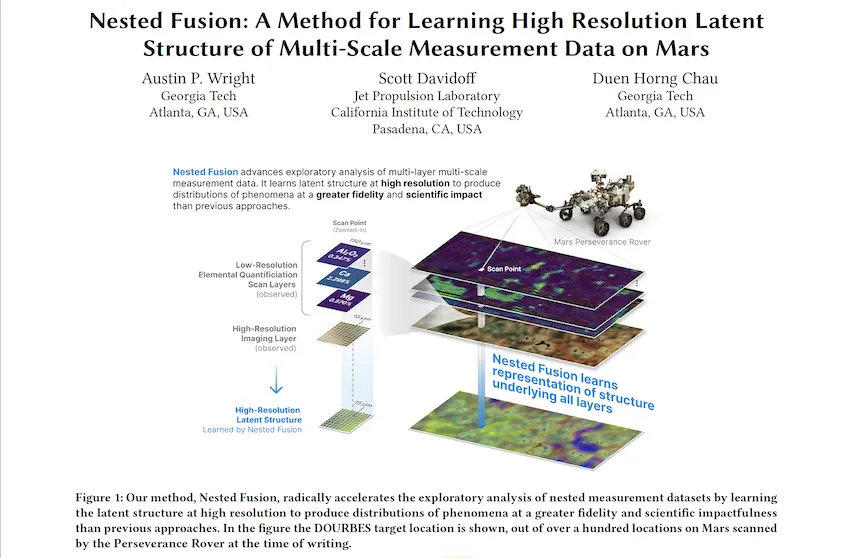
Nested Fusion combines datasets with different resolutions to produce a single, high-resolution visual distribution. Using this method, NASA scientists can more easily analyze multiple datasets from various sources at the same time. This can lead to faster studies of Mars’ surface composition to find clues of previous life.
The algorithm demonstrates how data science impacts traditional scientific fields like chemistry, biology, and geology.
Even further, Wright is developing Nested Fusion applications to model shifting climate patterns, plant and animal life, and other concepts in the earth sciences. The same method can combine overlapping datasets from satellite imagery, biomarkers, and climate data.
“Users have extended Nested Fusion and similar algorithms toward earth science contexts, which we have received very positive feedback,” said Wright, who studies machine learning (ML) at Georgia Tech.
“Cross-correlational analysis takes a long time to do and is not done in the initial stages of research when patterns appear and form new hypotheses. Nested Fusion enables people to discover these patterns much earlier.”
Wright is the data science and ML lead for PIXLISE, the software that NASA JPL scientists use to study data from the Mars Perseverance Rover.
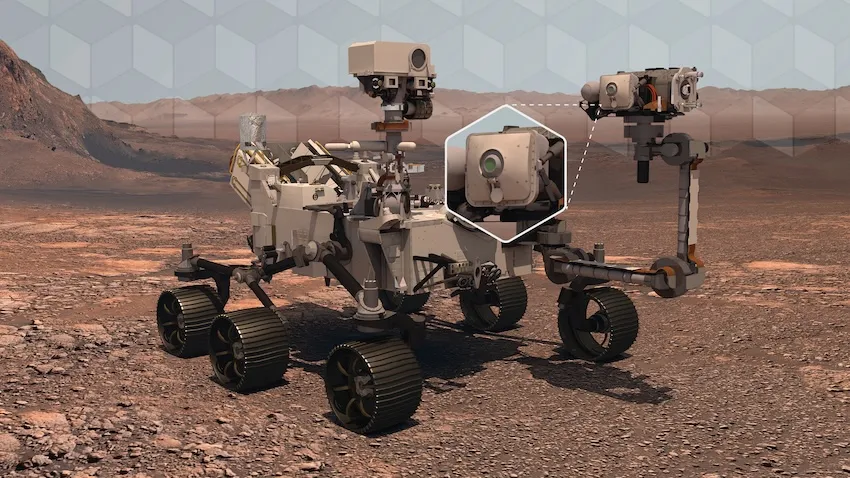
Perseverance uses its Planetary Instrument for X-ray Lithochemistry (PIXL) to collect data on mineral composition of Mars’ surface. PIXL’s two main tools that accomplish this are its X-ray Fluorescence (XRF) Spectrometer and Multi-Context Camera (MCC).
When PIXL scans a target area, it creates two co-aligned datasets from the components. XRF collects a sample's fine-scale elemental composition. MCC produces images of a sample to gather visual and physical details like size and shape.
A single XRF spectrum corresponds to approximately 100 MCC imaging pixels for every scan point. Each tool’s unique resolution makes mapping between overlapping data layers challenging. However, Wright and his collaborators designed Nested Fusion to overcome this hurdle.
In addition to progressing data science, Nested Fusion improves NASA scientists' workflow. Using the method, a single scientist can form an initial estimate of a sample’s mineral composition in a matter of hours. Before Nested Fusion, the same task required days of collaboration between teams of experts on each different instrument.
“I think one of the biggest lessons I have taken from this work is that it is valuable to always ground my ML and data science problems in actual, concrete use cases of our collaborators,” Wright said.
“I learn from collaborators what parts of data analysis are important to them and the challenges they face. By understanding these issues, we can discover new ways of formalizing and framing problems in data science.”
Wright presented Nested Fusion at KDD 2024, held Aug. 25-29 in Barcelona, Spain. KDD is an official special interest group of the Association for Computing Machinery. The conference is one of the world’s leading forums for knowledge discovery and data mining research.
Nested Fusion won runner-up for the best paper in the applied data science track, which comprised of over 150 papers. Hundreds of other papers were presented at the conference’s research track, workshops, and tutorials.
Wright’s mentors, Scott Davidoff and Polo Chau, co-authored the Nested Fusion paper. Davidoff is a principal research scientist at the NASA Jet Propulsion Laboratory. Chau is a professor at the Georgia Tech School of Computational Science and Engineering (CSE).
“I was extremely happy that this work was recognized with the best paper runner-up award,” Wright said. “This kind of applied work can sometimes be hard to find the right academic home, so finding communities that appreciate this work is very encouraging.”
News Contact
Bryant Wine, Communications Officer
bryant.wine@cc.gatech.edu